Powering Frontier AI with Uncompromised Human Intelligence in 200+ Languages
From foundational data annotation and custom data collection to advanced RLHF, SFT, and evaluation — we supply the human-in-the-loop infrastructure AI teams need to ship reliable models across 200+ languages, native dialects, and high-stakes regulated industries.
Talk to an AI Data Expert →Powering Frontier AI with Uncompromised Human Intelligence in 200+ Languages
From foundational data annotation and custom data collection to advanced RLHF, SFT, and evaluation — we supply the human-in-the-loop infrastructure AI teams need to ship reliable models across 200+ languages, native dialects, and high-stakes regulated industries.
Talk to an AI Data Expert
Full-Stack AI Data Pipeline
From high-volume multimodal annotation to complex cognitive alignment, we engineer the human infrastructure behind frontier AI.
Data Annotation
Transform raw data into accurate, high-quality labeled datasets designed to optimize machine learning performance, training, and model development.
Read MoreRLHF & Cognitive Alignment
Align AI models with human preferences through expert feedback, evaluation, reasoning, and structured cognitive alignment workflows.
Read MoreMultilingual SFT & Prompt Generation
Create multilingual supervised datasets and effective prompts that improve AI accuracy, fluency, contextual understanding, and performance.
Read MoreCustom Data Collection
Collect diverse, domain-specific datasets through customized workflows designed around your AI development goals, technical requirements, and business needs.
Read MoreAdversarial Red Teaming
Identify AI vulnerabilities through rigorous adversarial testing, edge-case analysis, safety evaluations, and challenging real-world scenarios.
Read MoreRAG & Output Validation
Strengthen retrieval-augmented generation through reliable data validation, factual evaluation, response verification, and comprehensive quality assurance processes.
Read More
Turning Raw Data
Into AI Intelligence.
Build reliable training datasets with precision annotation, expert review, multilingual coverage, and quality-controlled human intelligence.
Data that
teaches AI.
From computer vision and NLP to speech, text, video, and multimodal datasets, our annotation workflows transform complex raw data into structured AI-ready training assets.
Annotation Pipeline
Raw Data
Images, video, text, speech, documents, and multimodal AI training data.
AI-Ready Dataset
Structured, labeled, validated, and quality-controlled data ready for model training.
Teaching AI to
Think Better.
Align models with human preferences through expert feedback, preference optimization, reinforcement learning, and rigorous evaluation workflows.
From model output
to human-aligned
intelligence.
Expert evaluators provide the judgment models need to understand quality, relevance, safety, reasoning, and nuanced human preferences.
Cognitive Alignment Engine
Expert Preference Data
Capture high-quality human preferences across responses, reasoning, safety, accuracy, and domain-specific criteria.
RLHF & DPO Optimization
Transform preference signals into scalable optimization datasets for reinforcement learning and direct preference optimization.
Evaluation & Alignment
Benchmark model behavior against human expectations and continuously identify opportunities for improvement.
Safer, More Reliable Models
Deliver models that better understand context, follow instructions, reason consistently, and respond in alignment with intended human outcomes.
Build the human feedback infrastructure required to move frontier models from capable to reliable, aligned, and production-ready.
Explore RLHF & Cognitive Alignment →
Teach Models to
Speak Human.
Build stronger multilingual models with expert supervised fine-tuning, culturally aware prompt generation, and native-language human feedback.
From prompts
to production-ready
intelligence.
Create high-quality supervised fine-tuning datasets and multilingual prompts designed around real human communication, cultural context, domain terminology, and model-specific behavior.
Explore Multilingual SFT →Custom Data Collection Built for Smarter AI.
Build high-quality, purpose-driven datasets designed around your AI models, business objectives, and real-world use cases.
From multimodal data to specialized domain datasets, we collect, structure, validate, and prepare the data your AI systems need to perform reliably at scale.
Explore Data Collection ↗Datasets aligned with your AI objectives.
From focused projects to enterprise volumes.
Reliable and validated data at every stage.
Multilingual and geographically diverse data.
Adversarial Red Teaming
Put your AI systems to the test before real users do.
Identify hidden vulnerabilities, unsafe behaviors and unexpected model responses through structured adversarial testing designed to make AI systems more resilient, reliable and deployment-ready.
Attack Simulation
Real-world adversarial scenarios and edge cases.
Vulnerability Discovery
Expose weaknesses before they become business risks.
Model Safety Testing
Evaluate harmful, misleading and unexpected outputs.
RAG & Output Validation
Make AI responses more trustworthy by validating what the system retrieves, generates, and ultimately delivers.
Explore RAG Validation ↗Query
Understand the user's intent and identify the information required to answer it.
Retrieve
Measure whether relevant, high-quality context is retrieved from the knowledge source.
Generate
Evaluate whether the generated response accurately uses the retrieved evidence.
Validate
Check groundedness, relevance, completeness and output quality before acceptance.
Every response should earn trust.
A fluent answer is not necessarily a reliable answer. Validation helps determine whether generated content is actually supported by the retrieved context and aligned with the original query.
Relevant context from trusted sources.
Outputs supported by retrieved evidence.
Identify unsupported or fabricated claims.
Track quality as your AI system evolves.
Proprietary Datasets for Sovereign AI
Architecting foundation models for the world's most complex linguistic landscapes. We provide exclusive, ground-truth data infrastructure for native dialects, parallel corpora, and cultural alignment.
Indic Languages & Bharat Datasets
Capturing the deep linguistic diversity of India. We source, annotate, and align proprietary multilingual datasets across 22+ official Indian languages and hundreds of regional dialects, including Hindi, Tamil, Telugu, Marathi, and highly localized rural vernaculars. From specialized domain harvesting to massive parallel text corpora, we power the next generation of foundation LLMs.
Explore Indic Corpora →Dialectal Arabic & Khaleeji AI
Engineering culturally secure data for MENA's sovereign models. Beyond standard MSA, we provide deep, native-level data sourcing and RLHF alignment for complex regional dialects—including Khaleeji, Levantine, and Egyptian. We secure the semantic accuracy and cultural nuances required by top-tier Middle Eastern LLMs.
Explore Arabic Data →
Domain Expertise
for High-Stakes AI
Executing end-to-end AI data pipelines for complex, regulated industries through fully integrated global teams of domain experts and native linguists.
Healthcare &
Life Sciences
Validate clinical RAG outputs and annotate diagnostic imaging with precision, supported by verified medical professionals and specialized domain experts.
The Infrastructure Advantage
Architected for absolute precision, global scale, and uncompromised data security
Certified Domain Intelligence
Integrating certified doctors, legal specialists, and senior engineers directly into your pipeline to guarantee complex reasoning and factual grounding.
High-Volume Execution
Built for elastic scalability, processing massive datasets rapidly without ever breaching the strict quality thresholds required for frontier models.
Native Cultural Fluency
Securing absolute linguistic accuracy and cultural alignment across 200+ languages through our globally integrated, native-speaking teams.
Agnostic Workflow Integration
Operating seamlessly within your proprietary systems, or custom-architecting bespoke data pipelines tailored to your exact model requirements.
Secure AI. Accelerated
Time-to-Market.
Eliminate data bottlenecks without compromising proprietary assets. We provide the strict governance and high-volume throughput required to move foundation models from R&D to commercial deployment faster.
High-Fidelity Training Modalities
Purpose-built data environments tailored to the precise architecture of your foundation models.
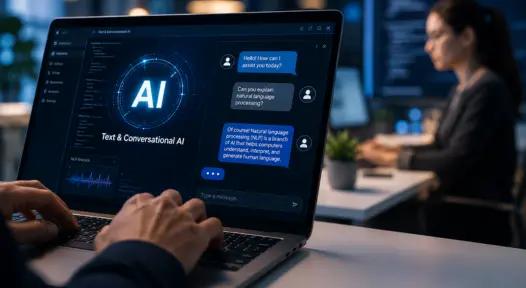
Text & Conversational
AI
Structuring complex multi-turn dialogue, logic-based reasoning chains (CoT), and deep linguistic alignment for global and sovereign LLMs.
Read More ♧
Vision & Spatial AI
Engineering pixel-perfect 2D/3D sensor fusion, semantic segmentation, and LiDAR point clouds for advanced perception systems.
Read More ♧
Speech & Audio
Intelligence
Architecting multi-speaker diarization, phonetic tagging, and studio-grade voice corpora across 200+ global dialects.
Read More ♧
Multimodal &
Embodied AI
Bridging text, vision, and sensor inputs to train highly accurate agentic workflows and real-world automated systems.
Read More ♧Enterprise Data Governance
Built on a strict zero-trust architecture to protect mission-critical IP at every stage of the AI lifecycle.
Regulatory Alignment
Operating under strict NDAs, GDPR compliance, and ISO-certified frameworks to ensure absolute global data sovereignty and risk mitigation.
Deterministic Quality Control
Executing multi-tier validation and Expert-in-the-Loop (HITL) consensus to guarantee hallucination-free, highly accurate training data.
Secure Infrastructure
Utilizing SOC-compliant workflows, air-gapped processing environments, and federated data pipelines to permanently eliminate data leakage.
Frequently Asked Questions
Explore essential insights into data annotation, Generative AI training, multimodal workflows, quality assurance and secure AI development.
Human data annotation is important for the Generative AI Training and LLM Training lifecycle. It transforms raw unstructured data into high quality datasets that allow large language models to understand language, context, intent, sentiment and reasoning. Expert annotators perform the labeling, classification and validation of text, images, audio and other data types to ensure consistency and accuracy across the whole training lifecycle. This structured data boosts every step of AI development, from data prep to Supervised Fine-Tuning (SFT), Reinforcement Learning from Human Feedback (RLHF), Direct Preference Optimization (DPO) – all allowing models to learn from quality human guidance, not just automated ones.
You also need human expertise to judge the quality of the AI responses, to find factual errors, reduce hallucinations and recognize bias, and to better align the models with human expectations in general. We also find continuous human feedback useful in real world use, to improve reasoning, response quality, and safety. Leveraging the power of human data annotation, rigorous quality assurance and domain expertise, organizations can develop AI systems that are more accurate, trustworthy and reliable. Generative AI is gaining traction across industries. The key to building scalable, ethical and high-performing large language models that provide consistent outcomes across languages, domains and user scenarios is high quality annotation.
Training Generative AI and creating good large language models require quality and accuracy at scale. It is based on clear annotation guidelines, expert human annotators, and standardized workflows to ensure consistency across large datasets. All annotation jobs are subject to strict quality guidelines and multi-level reviews, validation checks and expert audits to ensure that any inconsistencies are identified and corrected before the use of the data for model training. High quality datasets generated through sophisticated quality assurance processes, domain and native language experts provide performance boost for LLM Training, enabling complex use cases, verticals and languages.
Continuous feedback, performance monitoring, and human-in-the-loop validation throughout the AI lifecycle are also critical for scalable quality control. Annotations are validated by expert reviewers and the agreement of the annotators is quantified, and the guidelines are refined to ensure the consistency of outputs. This method provides high-quality and reliable training data for Supervised Fine-Tuning (SFT), Reinforcement Learning from Human Feedback (RLHF), Direct Preference Optimization (DPO) and AI model evaluation. This enables enterprises to reduce bias, minimize hallucinations, improve model accuracy, and build trustworthy Generative AI solutions that deliver consistent, context-aware, and human-aligned answers at enterprise scale.
Yes. Multi-modal Generative AI Training is the training of AI models to work with multiple types of data like text, voice, images and video. Premium Human Data Annotation Services for Tagging, Categorization & Validation of Any Type of Data to improve Model Learning & Performance. Text annotation improves understanding of language. Audio annotation can improve model speech recognition. Image annotation is useful for tasks such as object detection and visual reasoning. Video annotation helps the model to learn actions, events and contextual relations. The integration of these datasets enables LLM Training and multimodal AI systems to produce smarter, contextually aware and more accurate output for various real world applications.
We also have expert human reviewers and domain experts and a rigorous quality assurance process as part of a scalable multi-modal annotation workflow to ensure consistency across datasets. Human feedback is essential for Supervised Fine-Tuning (SFT), Reinforcement Learning from Human Feedback (RLHF), Direct Preference Optimization (DPO) and evaluation of AI models to reduce hallucinations, and to improve reasoning and safety. By incorporating quality annotations across text, voice, image and video, organizations can build trusted generative AI solutions to deploy across industries, languages and complex user interactions.
Learn how to create fair, accurate and responsible outputs from Generative AI Training models by tackling bias mitigation and safety compliance. High-quality human data annotation can help identify biased language, harmful content, misinformation, and sensitive information before datasets are used to train models. Clear annotation guidelines, diverse annotator teams and multi-level quality reviews help to increase consistency and reduce demographic, cultural and linguistic biases. These practices lead to balanced datasets that improve LLM Training and enable AI systems to deliver more reliable, inclusive, and context-aware responses across industries, languages, and user segments.
We improve safety compliance by continuous human evaluation, policy-based content review, and stringent quality assurance throughout the AI development life cycle. Expert annotators read the model outputs to check for safety and appropriateness, flagging any unsafe or inappropriate responses, and providing feedback for Supervised Fine-Tuning (SFT), Reinforcement Learning from Human Feedback (RLHF), Direct Preference Optimization (DPO), and AI model evaluation. Regular audits and continuous monitoring make the dataset’s quality better and reduce the number of hallucinations and harmful outputs. This human-in-the-loop approach helps organizations build trustworthy Generative AI solutions that are aligned to ethical standards, enable regulatory compliance and deliver safe, accurate and reliable AI experiences.
Security of Large Scale AI Training Generation For Sensitive And Confidential Data Annotation workflows are secured with access controls, role-based permissions, encrypted data transfer, and secure infrastructure to keep unauthorized access at bay. Strict security policies protect sensitive information. Annotators sign confidentiality agreements and protocols on a per-project basis. Data anonymization hides PII (Personally Identifiable Information) and employs access control to protect sensitive data. These security measures ensure that training data is protected throughout the annotation lifecycle enabling high quality LLM training in healthcare, finance, legal, and enterprise technology industries.
We also secure it through regular monitoring, periodic audits and rigorous quality assurance procedures to ensure data integrity and conformance to the industry standards. Reinforcement Learning from Human Feedback (RLHF), Supervised Fine-Tuning (SFT), Human annotator confirms annotation with confidence, Direct Preference Optimization (DPO), and AI model assessment all contribute to building trusted Generative AI solutions. Organizations can build trusted Generative AI solutions by focusing on strong data governance capabilities and human data annotation capabilities that protect proprietary data and comply with regulatory requirements to instill customer confidence throughout the AI development lifecycle.
Let’s Get On A Discovery Call
Ready to Scale Your
AI Infrastructure?
Connect with our data architecture team to discuss your proprietary model requirements.