Coznitiv

Expert RLHF, DPO & Preference Optimization

Enhance AI model alignment using expert human feedback, preference rankings, and scalable RLHF and DPO annotation workflows.

Talk to an AI Data Expert
Coznitiv AI

Enhance AI performance through RLHF, DPO, and expert human preference annotation.

Book a Strategy Session

Enhance AI performance through expert RLHF, DPO, and human preference annotation services. Our skilled annotators create high-quality preference datasets, ranking comparisons, and feedback loops that improve model alignment, reduce hallucinations, strengthen reasoning, and deliver safer, more accurate, and reliable AI systems for enterprise-scale applications.

8,000+
Certified Domain Experts.
200+
Languages & Dialects.
70+
Countries of Operation
15+
Years Of Excellence

Build Better LLMs with Human Preference Optimization

Align Outputs with Human
Intent

Reduce Hallucinations and
Improve Accuracy

Mitigate Bias ad Ensure
Ethical AI

Optimize for Long-Term
Performance

High-Fidelity Training Modalities

Purpose-built data environments tailored to the precise architecture of your foundation models.

Text & Conversational AI

Text & Conversational
AI

Structuring complex multi-turn dialogue, logic-based reasoning chains (CoT), and deep linguistic alignment for global and sovereign LLMs.

Read More â™§
Vision & Spatial AI

Vision & Spatial AI

Engineering pixel-perfect 2D/3D sensor fusion, semantic segmentation, and LiDAR point clouds for advanced perception systems.

Read More â™§
Speech & Audio Intelligence

Speech & Audio
Intelligence

Architecting multi-speaker diarization, phonetic tagging, and studio-grade voice corpora across 200+ global dialects.

Read More â™§
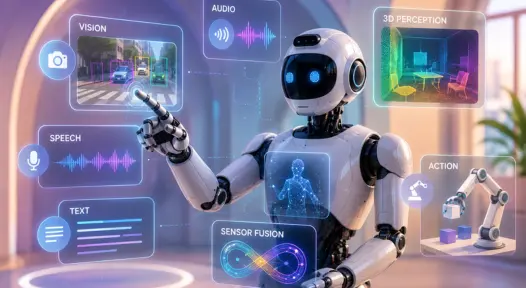
Multimodal & Embodied AI

Multimodal &
Embodied AI

Bridging text, vision, and sensor inputs to train highly accurate agentic workflows and real-world automated systems.

Read More â™§
What is Human Preference Optimization?

Human Preference Optimization (HPO) aligns AI models with human expectations by combining advanced optimization techniques with structured human feedback. This approach improves model accuracy, enhances response quality, reduces bias, and ensures AI systems deliver reliable, ethical, and user-centric outcomes.

✓ ★ + AI ✓ ↗

Reinforcement Learning from Human Feedback (RLHF) improves AI model behavior using expert human feedback and reward optimization, enabling models to generate more accurate, helpful, safe, and human-aligned responses across diverse real-world applications.

✓ A B ★ ✓ AI

Direct Preference Optimization (DPO) improves AI models by learning directly from ranked human preferences, delivering better alignment, higher-quality responses, and simpler training without complex reinforcement learning.

RLHF and DPO Process

RLHF + DPO Process

Our team of AI specialists delivers end-to-end RLHF services, ensuring high-quality, consistent, and reliable human feedback that helps your models learn, align, and perform with greater accuracy. Here’s how we support your AI journey.

Precise Feedback

Feedback Types & Reward Systems

  • Flexible Reward Models: Binary, rating scales, and custom reward systems.
  • Content Classification: Toxicity, bias, hallucinations, copyright, and safety labels.
  • Preference Ranking: Human comparisons to identify the best AI responses.
  • Structured Feedback: Consistent labels for reliable model training.

AI Response Evaluation

  • Quality Scoring: Accuracy, relevance, reasoning, and helpfulness.
  • Issue Detection: Identify bias, factual errors, toxicity, and hallucinations.
  • Actionable Insights: Clear explanations to improve model performance.
  • Scalable Reviews: High-quality human evaluation for continuous AI optimization.

Key Success Criteria
(KSC) Alignment

Define Success Metrics

We establish clear evaluation standards and quality benchmarks to ensure every annotation supports your AI objectives and delivers reliable training data.

Expert-Led Annotation

Our experienced annotators and domain specialists provide accurate, unbiased human feedback that improves model performance and alignment.

Comprehensive Quality
Checks

Every annotation passes through multiple validation stages to ensure accuracy, consistency, and dependable results at scale.

Custom Annotation
Frameworks

We develop project-specific guidelines that standardize annotations, reduce ambiguity, and ensure consistent outcomes across every AI training task.

Enterprise Data Governance

Built on a strict zero-trust architecture to protect mission-critical IP at every stage of the AI lifecycle.

Regulatory Alignment

Operating under strict NDAs, GDPR compliance, and ISO-certified frameworks to ensure absolute global data sovereignty and risk mitigation.

Deterministic Quality Control

Executing multi-tier validation and Expert-in-the-Loop (HITL) consensus to guarantee hallucination-free, highly accurate training data.

Secure Infrastructure

Utilizing SOC-compliant workflows, air-gapped processing environments, and federated data pipelines to permanently eliminate data leakage.

Frequently Asked Questions

Have questions? We’re here to help. Here are some of our most common queries.

Let’s Get On A Discovery Call

Ready to Scale Your
AI Infrastructure?

Connect with our data architecture team to discuss your proprietary model requirements.
AI Infrastructure Partnership
Scroll to Top