Challenge AI Models Before
Real-World Risks Emerge
Identify vulnerabilities, harmful behaviors, and unexpected model failures with expert-led Adversarial Red Teaming. Stress-test AI systems against challenging scenarios to improve safety, reliability, robustness, and real-world performance.
Talk to an AI Data Expert
Build Safer, More Reliable AI Systems with Advanced
Adversarial Red Teaming and Expert Human Evaluation
Book a Strategy Session
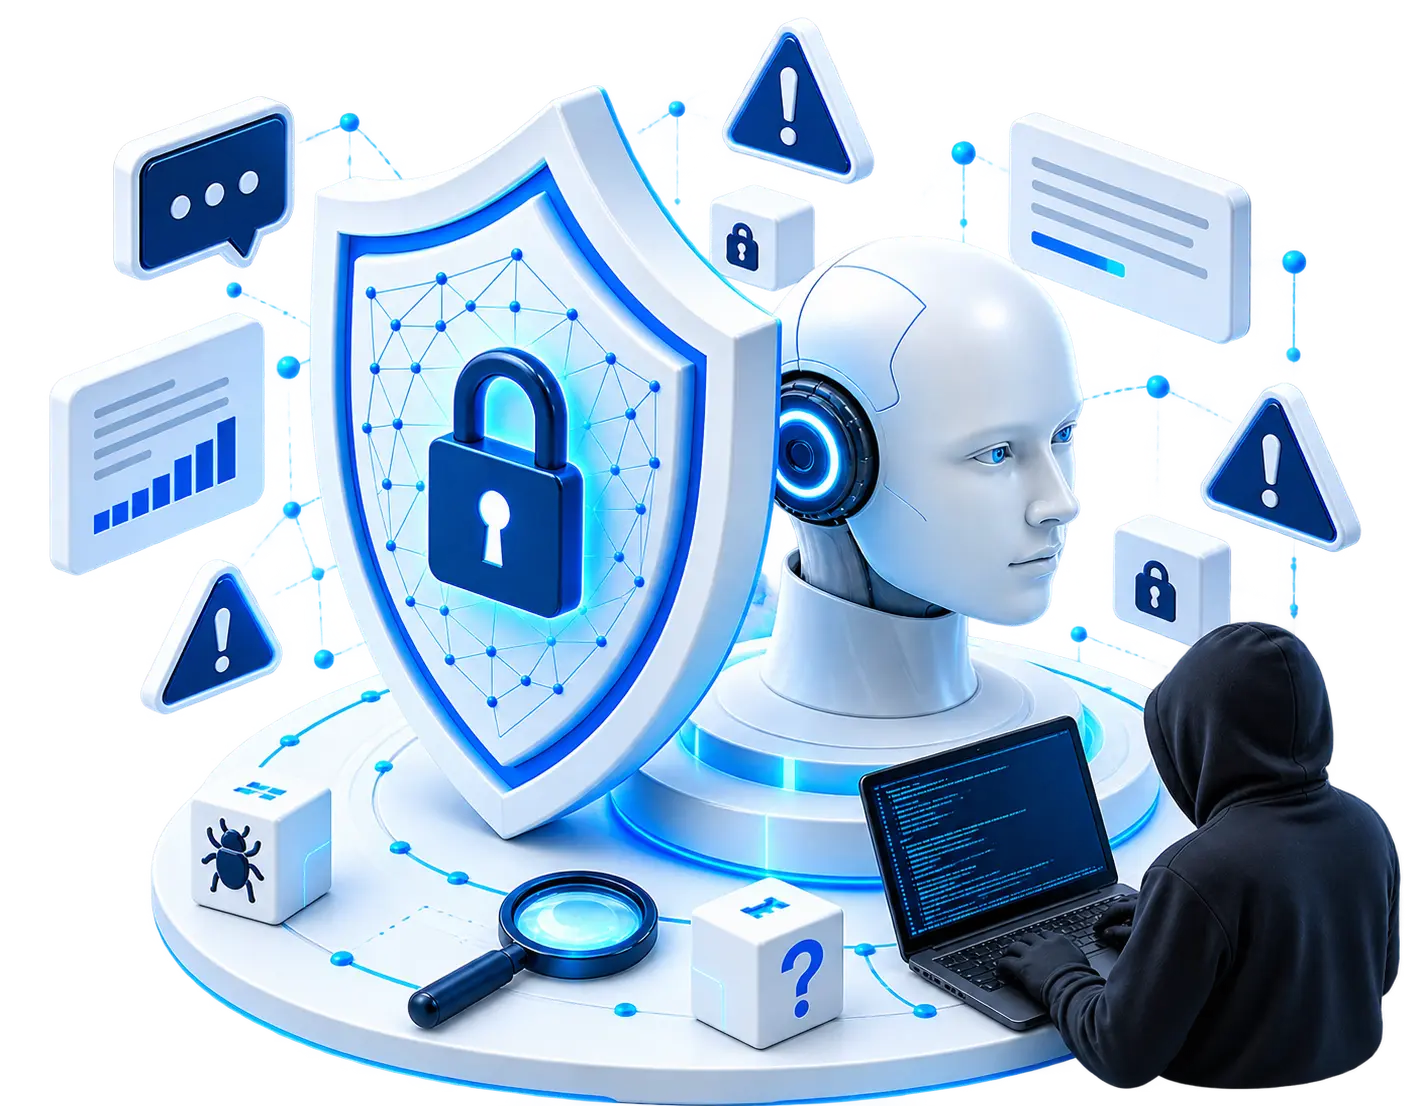
Strengthen your AI models and uncover vulnerabilities, harmful behaviors, hidden biases, hallucinations and security risks thru rigorous adversarial red teaming. Our expert human raters build challenging, real-world scenarios, test the limits of the model, and find potential failure modes that can be used to make the model safer, more robust, reliable, and responsible in a wide variety of applications and deployment settings.
Why Red Team Your AI Models?
Identify Vulnerabilities
Uncover hidden vulnerabilities and inaccuracies using carefully designed adversarial prompts.
Ensure Ethics + Bias Testing
Evaluate model compliance with ethical standards, handling of ambiguity, and ability to minimize bias.
Challenge with Real-World Scenarios
Apply conversational techniques and strategic prompts to evaluate model robustness and resilience.
Test Multimodal Performance Across Formats
Use realistic conversations and strategic techniques to assess model resilience and reliability.
High-Fidelity Training Modalities
Purpose-built data environments tailored to the precise architecture of your foundation models.
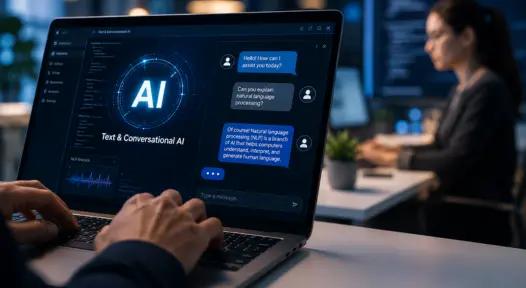
Text & Conversational
AI
Structuring complex multi-turn dialogue, logic-based reasoning chains (CoT), and deep linguistic alignment for global and sovereign LLMs.
Read More â™§
Vision & Spatial AI
Engineering pixel-perfect 2D/3D sensor fusion, semantic segmentation, and LiDAR point clouds for advanced perception systems.
Read More â™§
Speech & Audio
Intelligence
Architecting multi-speaker diarization, phonetic tagging, and studio-grade voice corpora across 200+ global dialects.
Read More â™§
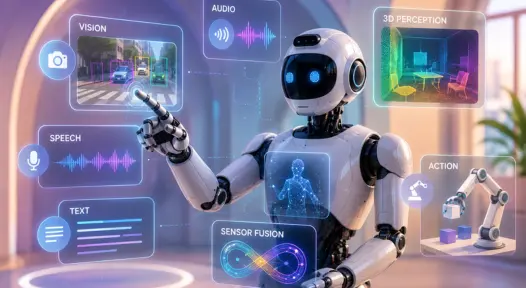
Multimodal &
Embodied AI
Bridging text, vision, and sensor inputs to train highly accurate agentic workflows and real-world automated systems.
Read More â™§AI Red Teaming Services
LLMs are powerful, yet they can produce unexpected or undesirable outputs. Our red teaming process rigorously tests models to uncover vulnerabilities, identify risks, and strengthen overall safety and reliability.
Talk to an Expert
ONE-TIME RED
TEAMING
Adversarial Prompt Creation for LLM Vulnerability Testing
Expert red teaming services create a specified quantity of prompts. Prompts aim to generate adverse responses from the model based on predefined safety vectors.
AUTOMATED RED
TEAMING
AI-Augmented Red Teaming Prompt Generation
Supplements manually-written prompts with AI-generated prompts that have been automatically identified as breaking model.
GENERATIVE AI
TESTING PLATFORM
Automated AI Model Safety Testing & Evaluation Platform
Designed for data scientists, the platform conducts automated testing of AI models, identifies vulnerabilities, and provides actionable insights to ensure models meet evolving regulatory standards and government compliance requirements.
CONTINUOUS /
ONGOING RED
TEAMING
Continuous LLM Red Teaming by Safety Vector
Continuous creation and delivery of prompts (e.g. monthly) for the ongoing assessment of model vulnerabilities.
HUMAN-GENERATED
RED TEAMING
Human Red Teaming – Prompt Writing & Response Rating
Adversarial prompts written by red teaming experts. Rating of model responses by experienced annotators for defined safety vectors using standard rating scales and metrics.
MULTIMODAL RED
TEAMING
Multimodal Red Teaming Prompt Writing
Adversarial prompts written to include multimodal elements including image, video, and speech/audio.
Enterprise Data Governance
Built on a strict zero-trust architecture to protect mission-critical IP at every stage of the AI lifecycle.
Regulatory Alignment
Operating under strict NDAs, GDPR compliance, and ISO-certified frameworks to ensure absolute global data sovereignty and risk mitigation.
Deterministic Quality Control
Executing multi-tier validation and Expert-in-the-Loop (HITL) consensus to guarantee hallucination-free, highly accurate training data.
Secure Infrastructure
Utilizing SOC-compliant workflows, air-gapped processing environments, and federated data pipelines to permanently eliminate data leakage.
Frequently Asked Questions
Have questions? We’re here to help. Here are some of our most common queries.
RLHF (Reinforcement Learning from Human Feedback), DPO (Direct Preference Optimization), and Preference Optimization are advanced techniques used in Generative AI Training to improve the quality, accuracy, and alignment of large language models. RLHF trains AI models using human feedback by rewarding preferred responses and discouraging poor ones, helping models generate more useful and context-aware outputs. DPO simplifies this process by learning directly from ranked human preferences without requiring a separate reward model, making optimization more efficient. Preference Optimization focuses on teaching AI systems to consistently produce responses that align with human expectations, improving reasoning, helpfulness, and overall user experience during LLM Training.
These methods rely on expert human data annotation, where annotators compare, rank, and evaluate multiple AI-generated responses based on accuracy, relevance, safety, and clarity. The collected feedback is used to refine model behavior, reduce hallucinations, minimize bias, and improve response consistency. Combined with Supervised Fine-Tuning (SFT) and AI model evaluation, RLHF, DPO, and Preference Optimization enable organizations to build reliable, trustworthy, and high-performing Generative AI models that deliver accurate and human-aligned results across diverse applications.
RLHF (Reinforcement Learning from Human Feedback) and DPO (Direct Preference Optimization) play a vital role in Generative AI Training by helping large language models produce responses that are more accurate, relevant, and aligned with human expectations. While pre-trained models learn from vast amounts of data, they still require human guidance to improve reasoning, reduce factual errors, and deliver context-aware answers. RLHF uses human feedback to reward preferred responses, whereas DPO directly learns from ranked human preferences, making the optimization process more efficient. Together, these methods significantly enhance the quality and reliability of LLM Training across a wide range of real-world applications.
Human data annotation is at the core of both RLHF and DPO, as expert annotators evaluate, compare, and rank multiple AI-generated responses based on accuracy, clarity, safety, and usefulness. This continuous feedback helps reduce hallucinations, minimize bias, improve consistency, and strengthen model alignment with user intent. Combined with Supervised Fine-Tuning (SFT) and AI model evaluation, RLHF and DPO enable organizations to develop trustworthy, high-performing Generative AI models that deliver safe, reliable, and human-centric experiences across industries and languages.
RLHF (Reinforcement Learning from Human Feedback) and DPO (Direct Preference Optimization) services are designed to improve the accuracy, safety, and alignment of AI models throughout the Generative AI Training lifecycle. These services include prompt creation, response ranking, preference annotation, pairwise comparison, quality evaluation, safety assessment, and structured human feedback. Expert annotators review AI-generated outputs to identify the most accurate, relevant, and contextually appropriate responses. This high-quality feedback helps refine LLM Training by improving reasoning, reducing hallucinations, and ensuring models generate reliable and human-aligned outputs across diverse domains and languages.
A comprehensive RLHF and DPO workflow also includes Supervised Fine-Tuning (SFT) support, AI model evaluation, bias detection, content moderation, and continuous quality assurance. Human reviewers validate annotations through multi-level quality checks to maintain consistency and accuracy at scale. These services enable organizations to optimize model performance, improve response quality, and enhance user satisfaction while meeting ethical AI standards. By combining expert human data annotation with rigorous evaluation processes, businesses can build trustworthy, scalable, and high-performing Generative AI models for enterprise and consumer applications.
Yes, multilingual RLHF (Reinforcement Learning from Human Feedback) and preference data collection are essential for developing Generative AI Training models that perform accurately across multiple languages and cultures. Native-language experts evaluate, compare, and rank AI-generated responses based on accuracy, fluency, cultural relevance, and contextual understanding. This human feedback helps large language models learn language-specific nuances, regional expressions, and user preferences that cannot be captured through automated processes alone. High-quality multilingual datasets improve LLM Training by enabling AI systems to generate natural, reliable, and context-aware responses for global users across diverse industries and markets.
A scalable multilingual annotation workflow includes preference ranking, pairwise comparisons, prompt evaluation, safety reviews, and rigorous quality assurance to ensure consistent results across languages. Human annotators also support Direct Preference Optimization (DPO), Supervised Fine-Tuning (SFT), and AI model evaluation by identifying the most helpful, accurate, and culturally appropriate responses. This continuous human feedback reduces bias, minimizes hallucinations, and improves model alignment with user expectations. As a result, organizations can build trustworthy, multilingual Generative AI solutions that deliver high-quality experiences across different languages, regions, and real-world applications.
High-quality RLHF (Reinforcement Learning from Human Feedback) and DPO (Direct Preference Optimization) datasets are built through well-defined annotation guidelines, expert human annotators, and rigorous quality assurance processes. Every task follows standardized instructions to ensure consistency when evaluating, comparing, and ranking AI-generated responses. Multi-level reviews, validation checks, and expert audits help identify inaccuracies and maintain annotation quality across large datasets. Native-language specialists and domain experts further improve the reliability of Generative AI Training by providing accurate, context-aware, and culturally relevant feedback that strengthens LLM Training and enhances model performance across different industries and languages.
Quality is continuously improved through human-in-the-loop workflows, ongoing reviewer calibration, and performance monitoring. Annotators assess responses for accuracy, relevance, clarity, safety, and alignment with user intent, while quality teams measure agreement scores and refine annotation guidelines when needed. These processes support Supervised Fine-Tuning (SFT), AI model evaluation, and preference optimization, helping reduce hallucinations, minimize bias, and improve reasoning capabilities. By combining expert human data annotation with scalable quality control, organizations can create reliable RLHF and DPO datasets that enable trustworthy, high-performing Generative AI models.
Let’s Get On A Discovery Call
Ready to Scale Your
AI Infrastructure?
Connect with our data architecture team to discuss your proprietary model requirements.