Expert RLHF, DPO & Preference Optimization
Enhance AI model alignment using expert human feedback, preference rankings, and scalable RLHF and DPO annotation workflows.
Talk to an AI Data Expert
Enhance AI performance through RLHF, DPO, and expert human preference annotation.
Book a Strategy SessionEnhance AI performance through expert RLHF, DPO, and human preference annotation services. Our skilled annotators create high-quality preference datasets, ranking comparisons, and feedback loops that improve model alignment, reduce hallucinations, strengthen reasoning, and deliver safer, more accurate, and reliable AI systems for enterprise-scale applications.
Build Better LLMs with Human Preference Optimization
Align Outputs with Human
Intent
Reduce Hallucinations and
Improve Accuracy
Mitigate Bias ad Ensure
Ethical AI
Optimize for Long-Term
Performance
High-Fidelity Training Modalities
Purpose-built data environments tailored to the precise architecture of your foundation models.
Text & Conversational
AI
Structuring complex multi-turn dialogue, logic-based reasoning chains (CoT), and deep linguistic alignment for global and sovereign LLMs.
Read More â™§
Vision & Spatial AI
Engineering pixel-perfect 2D/3D sensor fusion, semantic segmentation, and LiDAR point clouds for advanced perception systems.
Read More â™§
Speech & Audio
Intelligence
Architecting multi-speaker diarization, phonetic tagging, and studio-grade voice corpora across 200+ global dialects.
Read More â™§
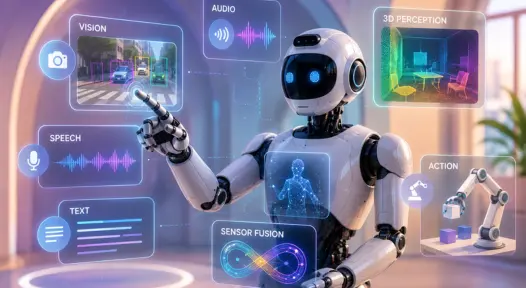
Multimodal &
Embodied AI
Bridging text, vision, and sensor inputs to train highly accurate agentic workflows and real-world automated systems.
Read More â™§What is Human Preference Optimization?
Human Preference Optimization (HPO) aligns AI models with human expectations by combining advanced optimization techniques with structured human feedback. This approach improves model accuracy, enhances response quality, reduces bias, and ensures AI systems deliver reliable, ethical, and user-centric outcomes.
Reinforcement Learning from Human Feedback (RLHF) improves AI model behavior using expert human feedback and reward optimization, enabling models to generate more accurate, helpful, safe, and human-aligned responses across diverse real-world applications.
Direct Preference Optimization (DPO) improves AI models by learning directly from ranked human preferences, delivering better alignment, higher-quality responses, and simpler training without complex reinforcement learning.
RLHF + DPO Process
Our team of AI specialists delivers end-to-end RLHF services, ensuring high-quality, consistent, and reliable human feedback that helps your models learn, align, and perform with greater accuracy. Here’s how we support your AI journey.
Precise Feedback
Feedback Types & Reward Systems
- Flexible Reward Models: Binary, rating scales, and custom reward systems.
- Content Classification: Toxicity, bias, hallucinations, copyright, and safety labels.
- Preference Ranking: Human comparisons to identify the best AI responses.
- Structured Feedback: Consistent labels for reliable model training.
AI Response Evaluation
- Quality Scoring: Accuracy, relevance, reasoning, and helpfulness.
- Issue Detection: Identify bias, factual errors, toxicity, and hallucinations.
- Actionable Insights: Clear explanations to improve model performance.
- Scalable Reviews: High-quality human evaluation for continuous AI optimization.
Key Success Criteria
(KSC) Alignment
Define Success Metrics
We establish clear evaluation standards and quality benchmarks to ensure every annotation supports your AI objectives and delivers reliable training data.
Expert-Led Annotation
Our experienced annotators and domain specialists provide accurate, unbiased human feedback that improves model performance and alignment.
Comprehensive Quality
Checks
Every annotation passes through multiple validation stages to ensure accuracy, consistency, and dependable results at scale.
Custom Annotation
Frameworks
We develop project-specific guidelines that standardize annotations, reduce ambiguity, and ensure consistent outcomes across every AI training task.
Enterprise Data Governance
Built on a strict zero-trust architecture to protect mission-critical IP at every stage of the AI lifecycle.
Regulatory Alignment
Operating under strict NDAs, GDPR compliance, and ISO-certified frameworks to ensure absolute global data sovereignty and risk mitigation.
Deterministic Quality Control
Executing multi-tier validation and Expert-in-the-Loop (HITL) consensus to guarantee hallucination-free, highly accurate training data.
Secure Infrastructure
Utilizing SOC-compliant workflows, air-gapped processing environments, and federated data pipelines to permanently eliminate data leakage.
Frequently Asked Questions
Have questions? We’re here to help. Here are some of our most common queries.
RLHF (Reinforcement Learning with Human Feedback) DPO (Direct Preference Optimization) Generative AI Training Advanced techniques to improve quality, accuracy and alignment of large language models Preference Optimization RLHF: RLHF is a method of training AI models using feedback from people. The models are trained to give more useful and contextual answers, rewarding better answers and punishing worse ones. This process is simplified because DPO learns directly from ranked human preferences, removing the need for a separate reward model, and thus being more efficient for optimization. Time to train a llm: Preference Optimization: It trains LLMs to better match human preferences, helping LLMs to be better at reasoning, more helpful, and improving the overall user experience.
These methods are data annotation by human experts who compare, rank and evaluate multiple AI responses on accuracy, relevance, safety and clarity. We’re also working hard to reduce hallucinations, bias and improve consistency in responses – the feedback we collect helps us improve model behavior. Supervised Fine Tuning (SFT) and AI model evaluation combined with RLHF, DPO and Preference Optimization enable organizations to build reliable, trustworthy, high-performing Generative AI models that can produce accurate and human-aligned output for various applications.
RLHF (Reinforcement Learning from Human Feedback) and DPO (Direct Preference Optimization) are two of the most important techniques used in training Generative AI to make large language models produce more accurate, relevant and aligned outputs with human expectations. Pre-trained models are trained on large datasets, but require human input to improve reasoning, reduce factual error and produce contextually relevant answers. RLHF trains the reward from human feedback DPO learns directly from ranked human preferences, and can be optimized more efficiently. These methods enhance the quality and reliability of LLM Training and thus have a wide range of applications to real world problems.
Both RLHF and DPO need humans to label data . The AI model's multiple responses are graded, compared and ranked by expert labelers based on accuracy, clarity, safety and helpfulness. Continuous feedback can help to reduce hallucination and bias, increase consistency and improve model alignment with user intent Alongside RLHF and DPO, Supervised Fine-Tuning (SFT) and AI model evaluation allow organizations to develop Generative AI models that are trustworthy, high-performing and deliver safe, reliable and human-centric experiences across industries and languages.
RLHF (Reinforcement Learning from Human Feedback) and DPO (Direct Preference Optimization) services can be used to improve the accuracy, safety and alignment of AI models to improve the Generative AI Training lifecycle. The services are: fast generation, response ranking, preference labeling, pairwise comparison, quality evaluation and safety evaluation, structure human feedback. Expert annotators review the ai’s outputs and select the most accurate, relevant and contextually appropriate outputs. This high quality feedback feeds into LLM Training to enable better reasoning, less hallucinations and to ensure models produce reliable, human aligned output across diverse domains and languages.
The RLHF and DPO process is a full package which also includes Supervised Fine Tuning (SFT), AI model evaluation, bias discovery, content filtering and ongoing quality monitoring. To ensure scale and accuracy, humans conduct multiple levels of quality checks on the annotations for consistency. These services are intended to enhance models’ performance, the quality of the responses, and user satisfaction in a manner consistent with ethical AI. Companies can build trustworthy, scalable and high-performance Generative AI models to power their enterprise and consumer applications by utilizing expert human data annotation and robust evaluation processes.
To train generative AI models to be accurate across languages and cultures, we need multi-lingual reinforcement learning from human feedback and preference data collection. AI generated responses are rated and compared by native expert reviewers on Accuracy, Fluency, Cultural Relevance and Understanding of Context. “Combined with human feedback, large language models can learn language-specific nuances, regional phrases, and user preferences that cannot be learned by automated processes alone. High quality multi-lingual datasets are key to training LLMs, so that the AI system can provide natural, reliable and context-aware responses to the users across industries and markets worldwide.
We propose a scalable workflow for multilingual annotation that includes preference ranking, pairwise comparisons, prompt evaluation, safety reviews, and quality assurance, to unify results across languages. Human annotators also assist with Direct Preference Optimization (DPO), Supervised Fine-Tuning (SFT) and AI model evaluation to surface the most useful, accurate and culturally appropriate responses. And that continuous feedback from humans helps reduce bias. And it cuts down on hallucinations and helps the model better match the expectations of the user. This allows organizations to deploy trusted multilingual Generative AI solutions that deliver high-quality experiences across languages, regions, and real-world use cases.
We create high quality datasets for RLHF (Reinforcement Learning from Human Feedback) and DPO (Direct Preference Optimization) with clear annotation guidelines, professional human annotators and rigorous quality control procedures. Each task is accompanied by standardized instructions to enable consistent assessment, comparison and ranking of the AI-generated responses. Multi-level reviews, validation checks and expert audits help in identifying inaccuracies and quality of annotations in large data sets. LLM Training is enabled by high-quality, context-sensitive and culturally-relevant feedback from native language specialists and domain experts. This improves Generative AI Training and the performance of models across different industries and languages.
Human-in-the-loop workflows for continuous quality improvement Ongoing calibration and monitoring of reviewers’ performance. Annotators score the responses based on correctness, relevance, clarity, safety and adherence to user intent and quality teams monitor inter-annotator agreement and revise annotation guidelines if needed These processes are used for Supervised Fine-Tuning (SFT), evaluation and preference optimization of AI models. This decreases hallucinations, reduces biases and increases reasoning capabilities. With expert human data annotation, scalable quality control and trusted datasets for RLHF and DPO, organizations can build trustworthy, high-performing Generative AI models.<br/><br/>
Let’s Get On A Discovery Call
Ready to Scale Your
AI Infrastructure?
Connect with our data architecture team to discuss your proprietary model requirements.